All work

The Epstein Index

A searchable, OCR’d archive of the released Epstein case files.

Source on GitLab Python · v0.8.0
Isometric row of the eight numbered stages of the epstein_index pipeline, from 1 download at the back left to 8 prepare at the front right: download, organize, read, delineate, clean, extract, analyze, prepare. Where a stage writes to its own data directory, the files it leaves are a stack of plates, one plate per 10,000 files and the top plate drawn to its fraction. Counted files: 106,119 after download, 105,023 after read, 56,778 after delineate, 56,778 after clean, 40,469 after extract, 8 after analyze, and 34,695 documents in the site content after prepare. The read stage runs two OCR engines; its stack counts data/ocr only, and the second engine's data/ocr-marker2 (112,555 files) is not drawn. The directories hold different kinds of file (raw PDFs and media, OCR pages, documents), so the heights compare directory sizes, not one population passing through. Organize moves files inside a directory tree and has no output directory of its own, so it is a bare plate with no stack. 1 download 2 organize 3 read 4 delineate 5 clean 6 extract 7 analyze 8 prepare 106k 105k 57k 57k 40k 8 files 35k 1 plate = 10,000 files

The Epstein Index makes the released Epstein case files readable and searchable. An eight-stage Python pipeline downloads, OCRs, cleans, and organizes the source documents; an Astro site serves them with timelines, maps, topic views, and a network plot.

Its v1.1.0 release serves 34,695 pages drawn from nearly 57,000 cleaned documents, and every derived claim traces back to its OCR source. Privacy screening and a takedown holdlist run before anything is published.
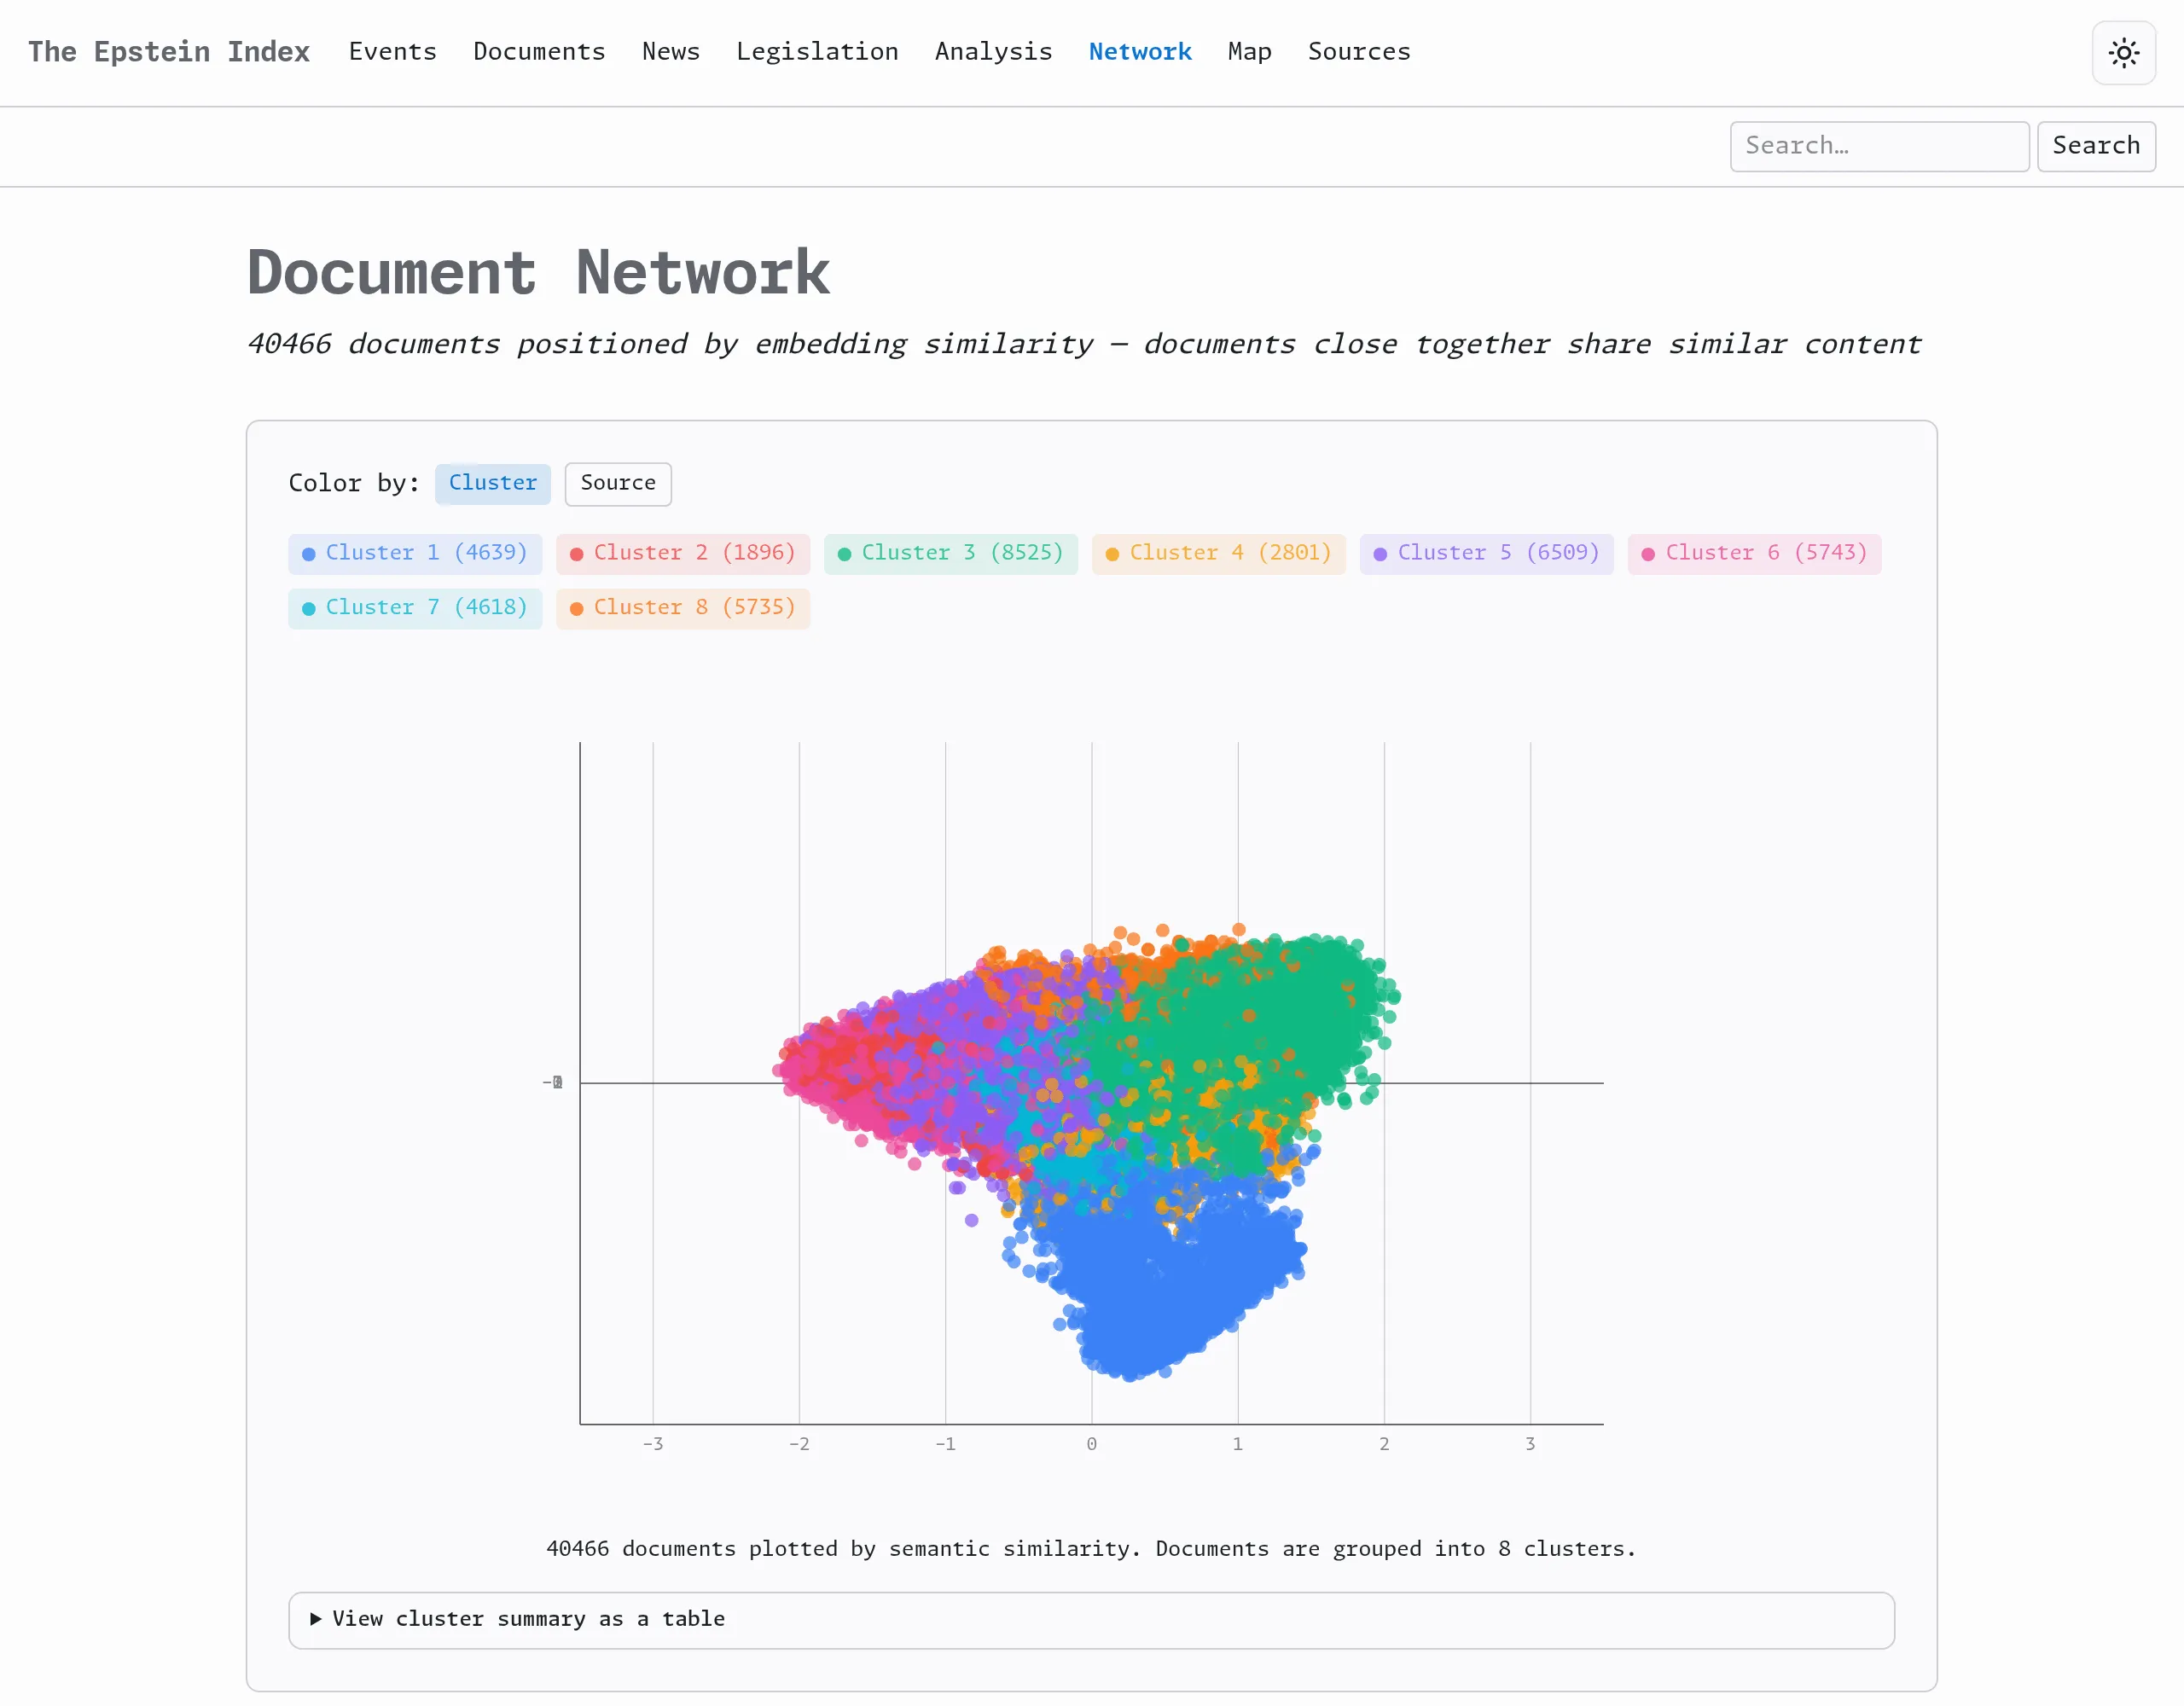
The Epstein Index document network: 40,466 documents plotted by embedding similarity as a scatter of eight colored clusters.
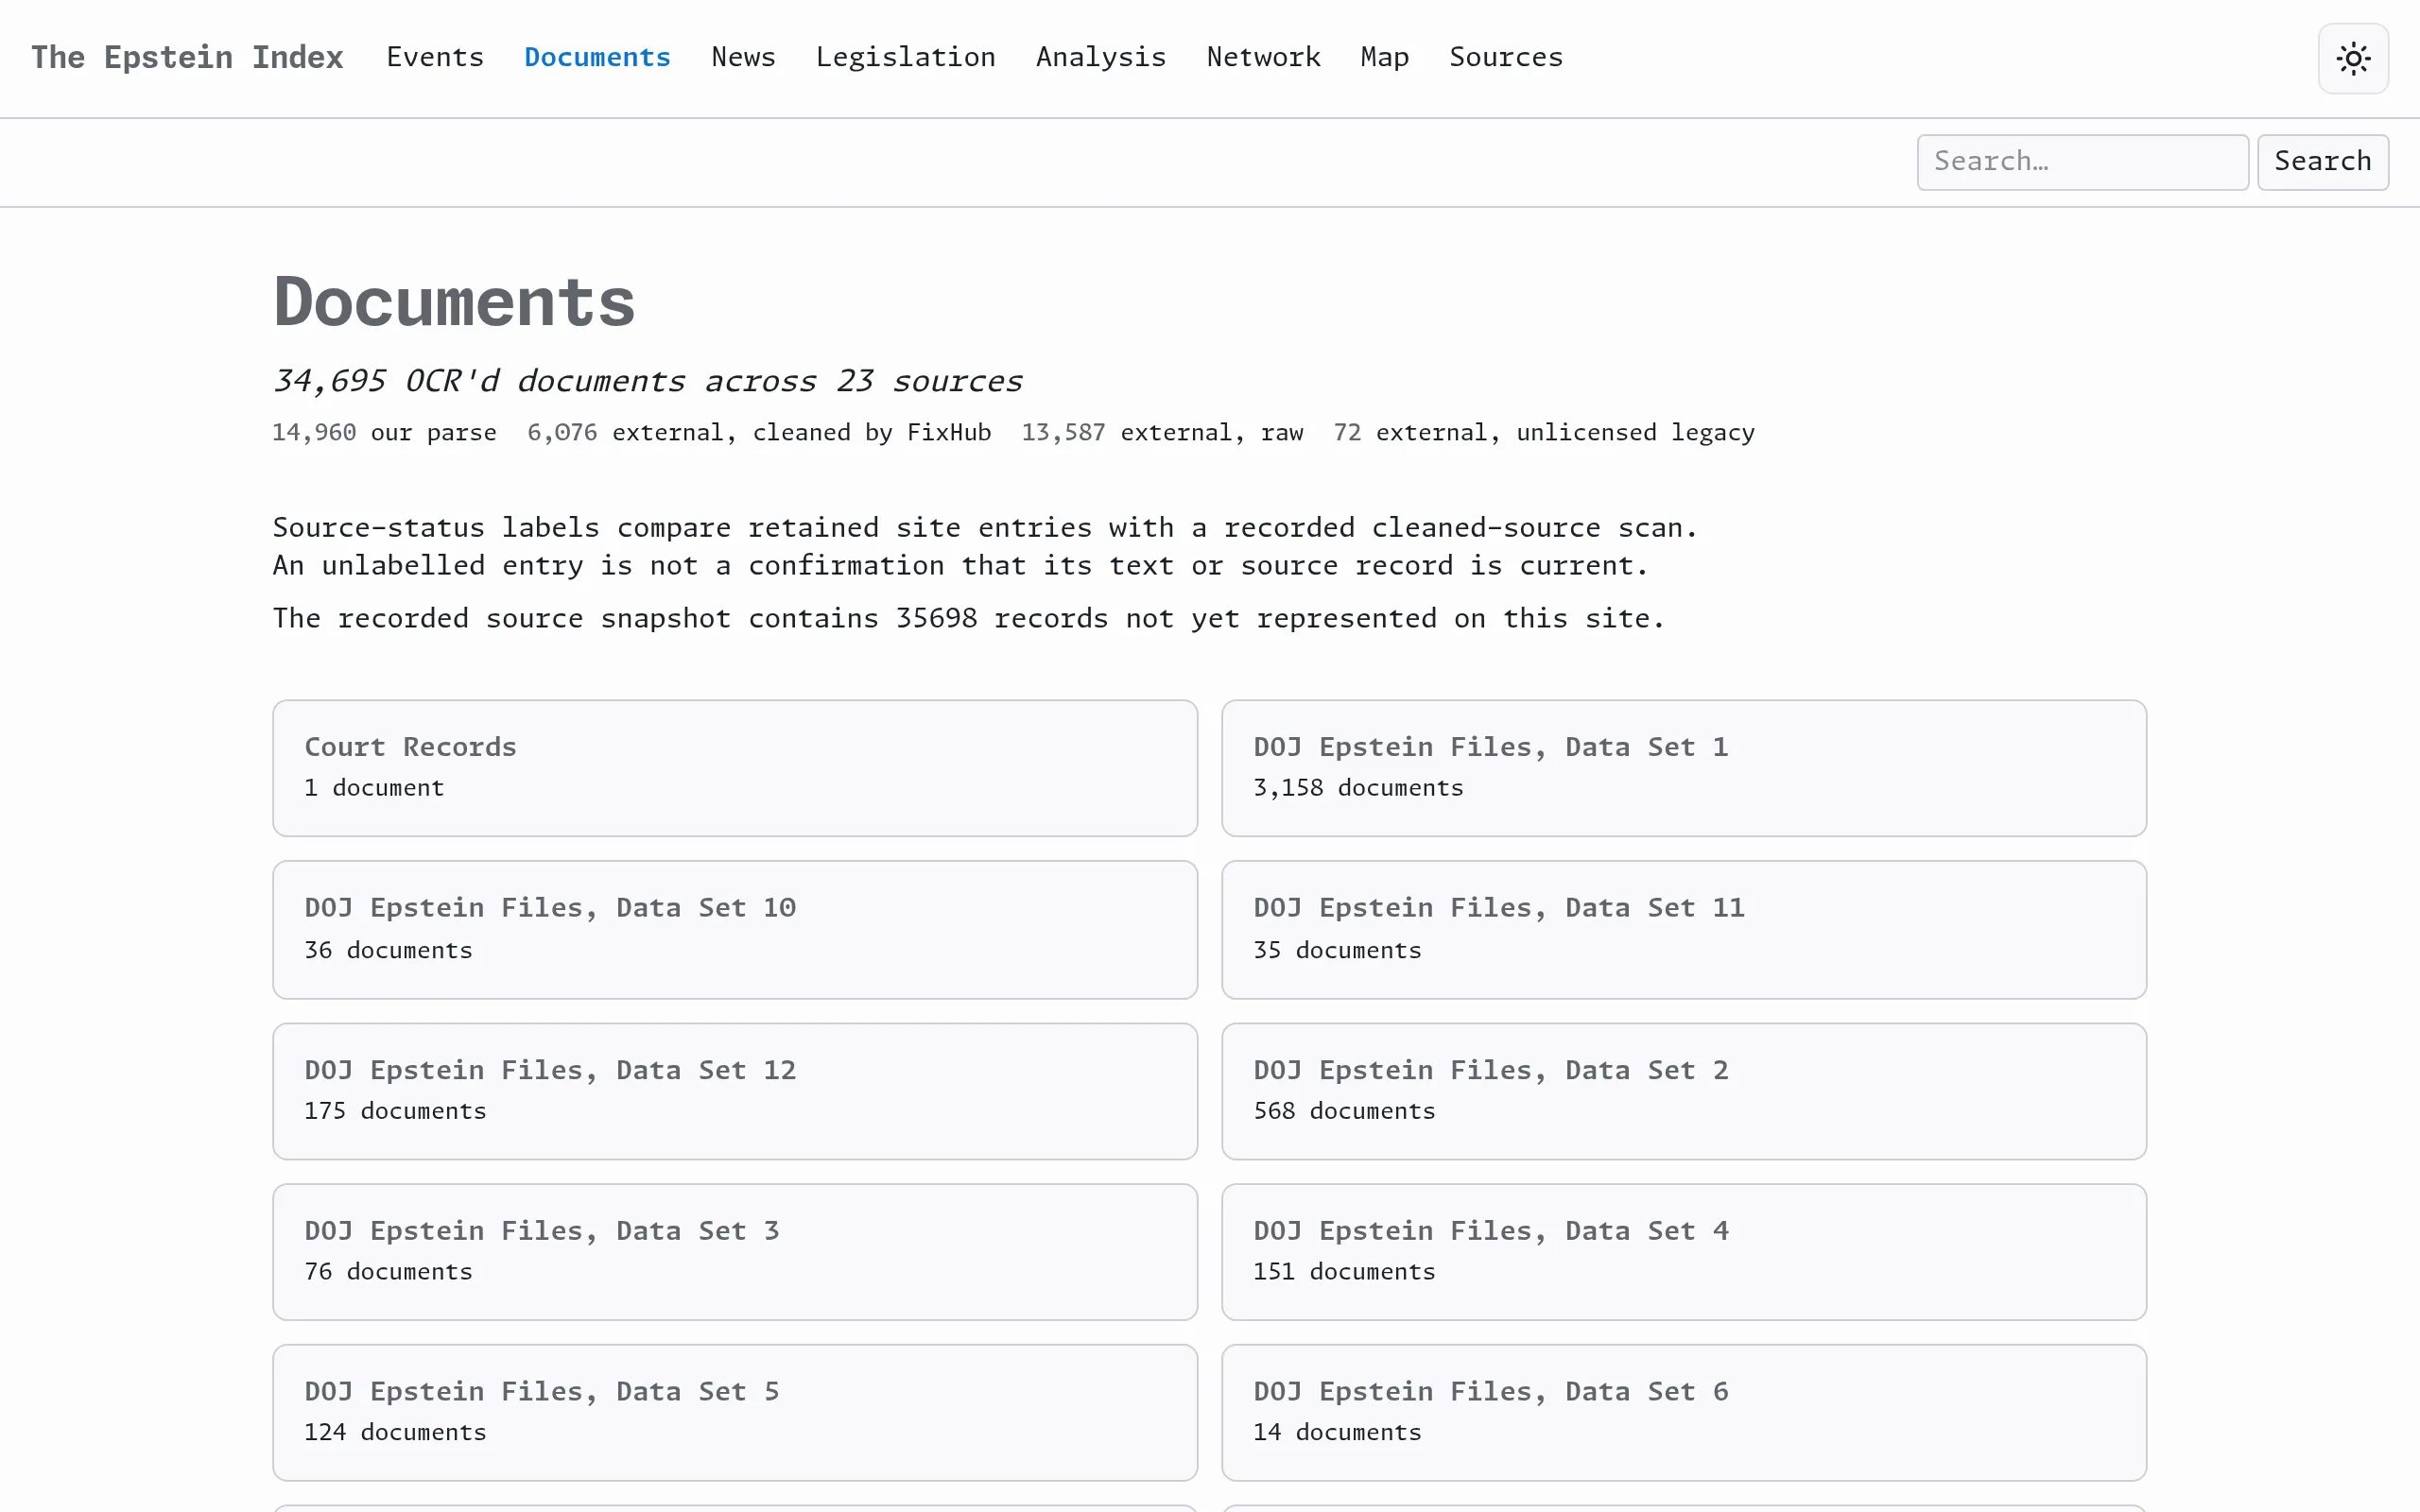
The manifest backing the site's 34,695 published pages (v1.1.0) breaks them into four disclosed tiers: 14,960 pages are this project's own OCR parse (marker-pdf 1.5.5 + surya-ocr 0.12.1 baseline), while 6,076 are external text cleaned by FixHub, 13,587 are external raw text, and 72 are external unlicensed-legacy mirror text. Each tier is labeled on the site rather than presented as one uniform pipeline. our parse (marker-pdf + surya-ocr) 14,960 external, cleaned by FixHub 6,076 external, raw 13,587 external, unlicensed legacy 72 site pages 34,695 v1.1.0
The Epstein Index documents page listing source collections, such as DOJ data sets, with document counts.
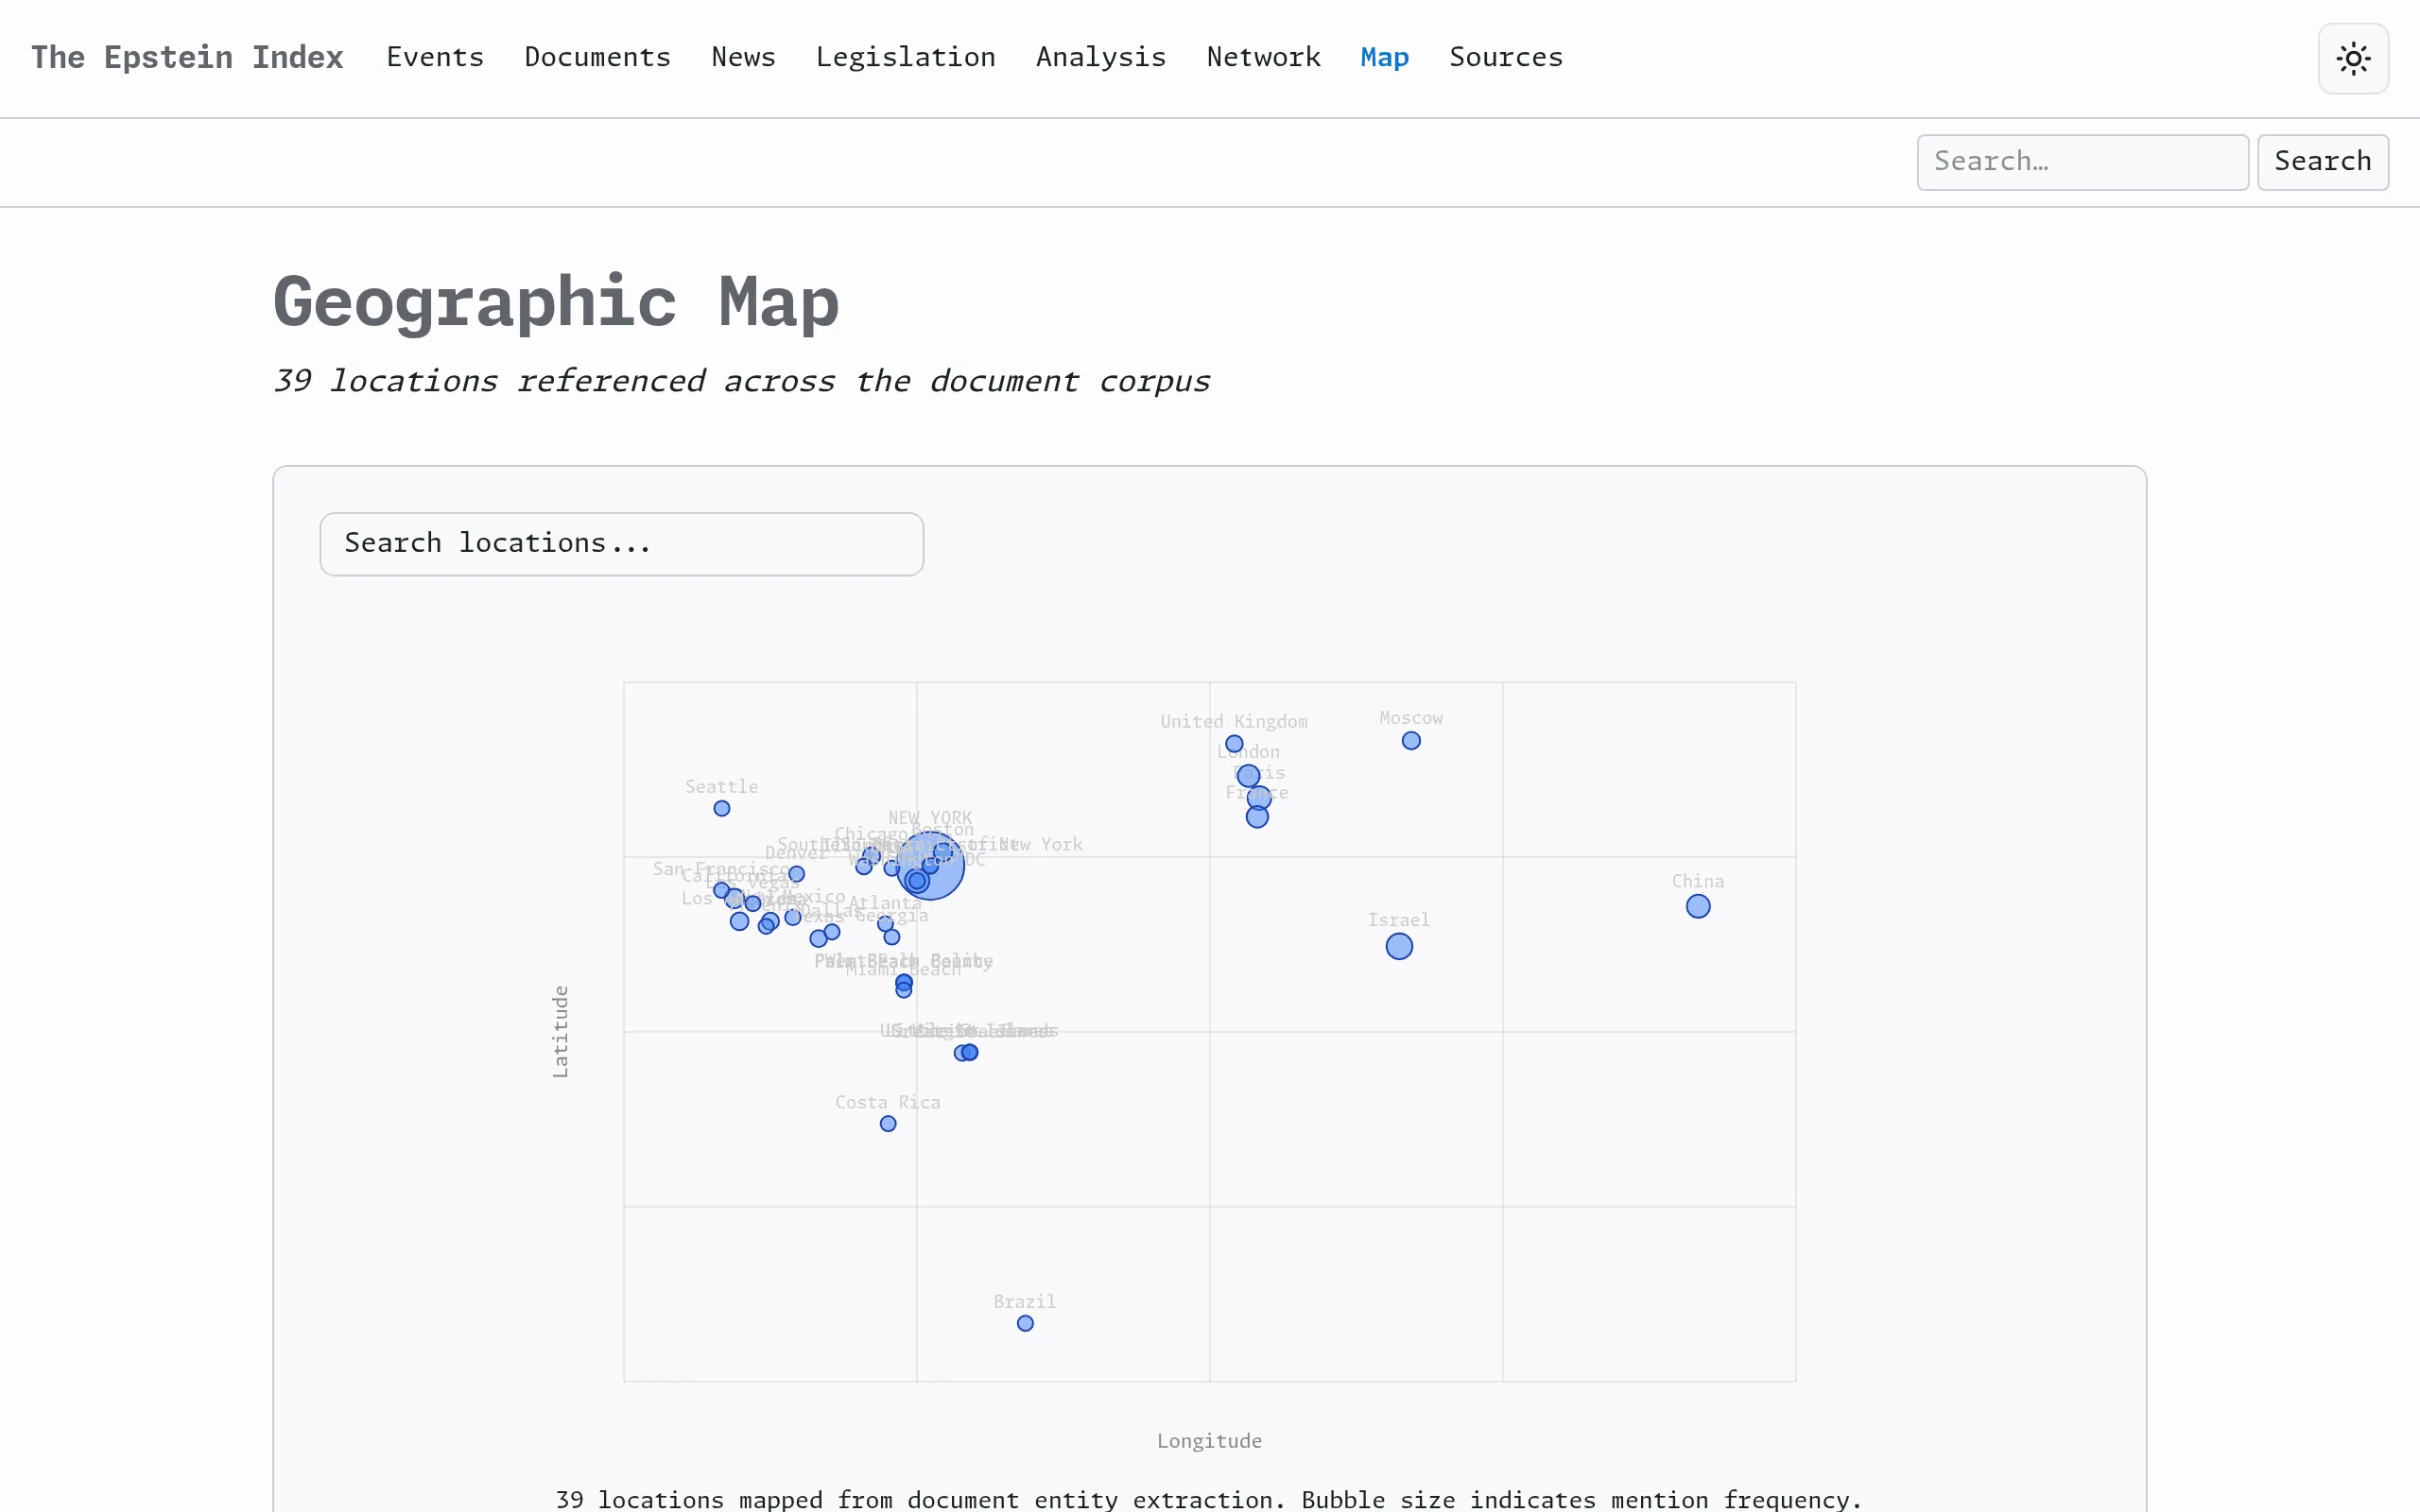
The Epstein Index geographic map plotting 39 locations referenced across the document corpus.